Sonnet 5.5 is fast, ChatGPT is cheap
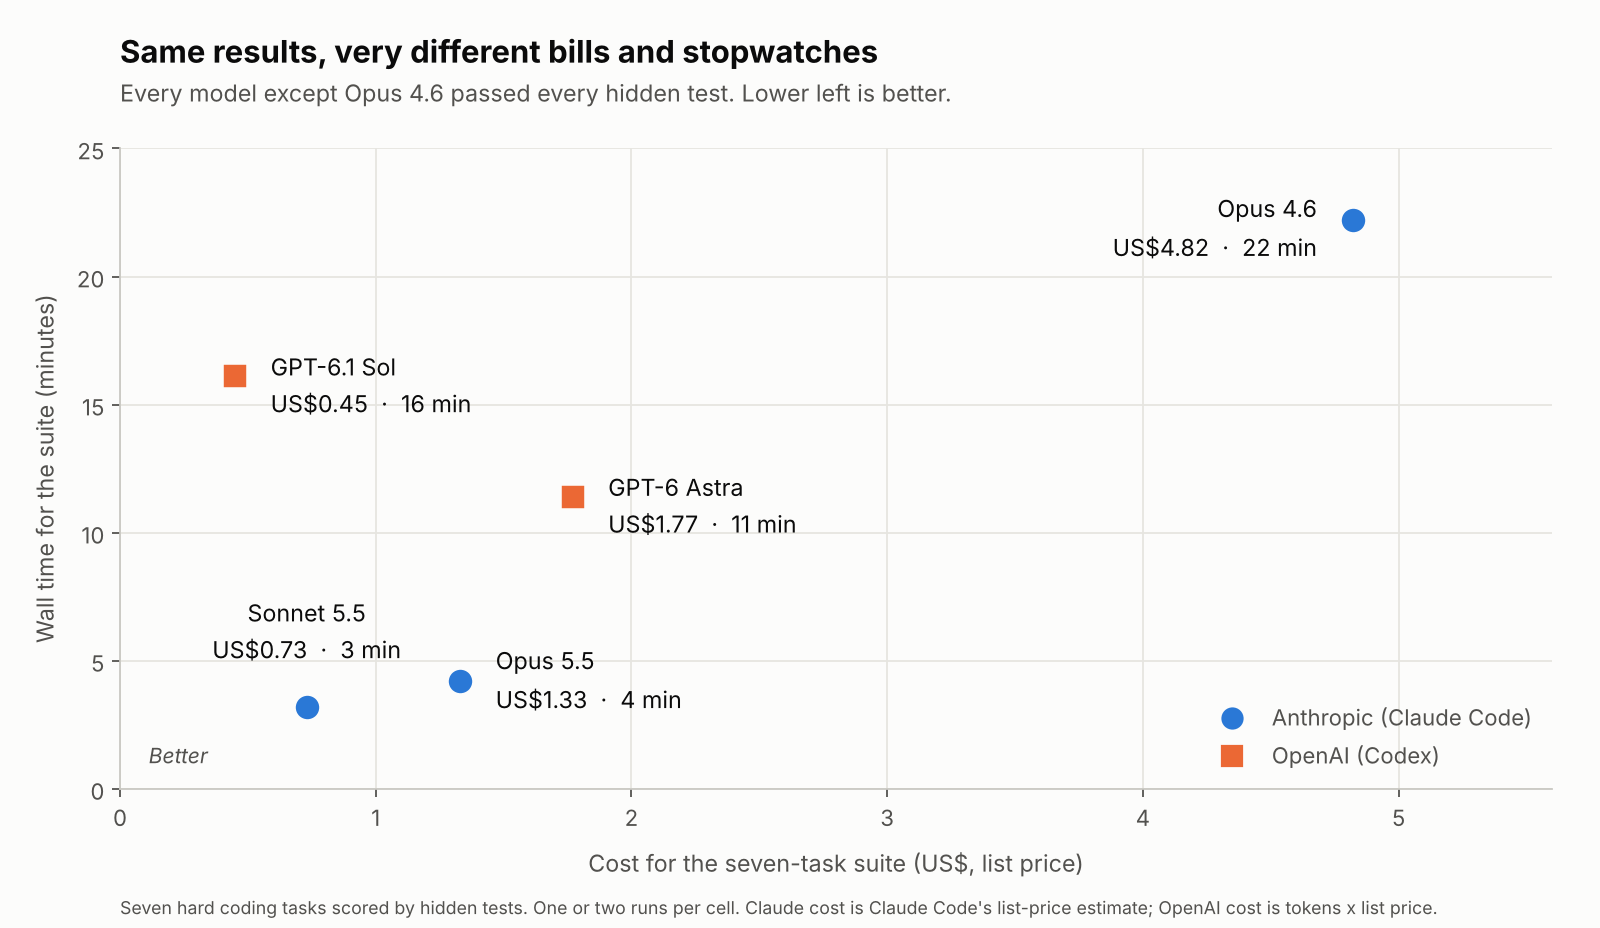
I ran the same seven hard coding tasks through five models. Every current model passed every test. The only things that differed were the bill and the stopwatch.
The short version
Think of it as a driving test for AI coding assistants. I gave five of them the same seven hard programming jobs and marked the results with tests they could not see.
Four passed every job: Claude Sonnet 5.5, Claude Opus 5.5, ChatGPT’s GPT-6.1 Sol and GPT-6 Astra. The older Claude Opus 4.6 got two of its 14 attempts wrong. So the choice is not about quality. It is about money and time.