Sonnet writes better research drafts, Haiku writes them for a cent
TLDR

The test. Haiku 5.5 and Sonnet 5.5 each wrote nine research drafts from identical source packs, using one fixed template. Two AI judges compared them blind, 27 verdicts in all.

The result. Sonnet won 16 verdicts and Haiku 11. Sonnet is better at insight, accuracy and readability. Coverage is tied. Neither model invented a quote.

The twist. It depends on the sources. Sonnet won 15 of 18 verdicts on messy news-style packs by cross-checking and catching errors. Haiku won 8 of 9 on a dense documentation pack, where breadth is the job.

The price. About one US cent a draft for Haiku and nine cents for Sonnet.

My take. Haiku for first-pass drafts on well-organised sources. Sonnet when the sources disagree or might be wrong.
Continue reading →


For coding Haiku 5.5 matches Sonnet at a tenth of the price

Anthropic released Claude Haiku 5.5 overnight, and the pace has not eased. Last year’s small model, Haiku 4.5, cost US$1 in and US$5 out per million tokens. Haiku 5.5 is US$0.10 and US$0.50, a tenth of the price, and Anthropic calls it its cheapest, fastest and most capable small model yet.

That is the pattern across the whole industry this year. Often each release is cheaper and quicker than the last, and every lab is pushing the others. OpenAI’s GPT-6 Luna sits at exactly the same price and appears in Anthropic’s own comparison table. Competition is working, and we are the ones collecting the winnings.

Continue reading →


Rubber Soul at 61 gets a fresh mix

Rubber Soul has been lopsided for 61 years. On the 1965 stereo mix the voices are parked on one side and the instruments are scattered across the rest. On headphones it is like eavesdropping on two different rooms. On 2 October that changed. Giles Martin and engineer Sam Okell released a new stereo mix on Apple Music, rebuilt from the original four-track tapes. It is also on Spotify. I haven’t done my proper listen yet.

Continue reading →


Sonnet 5.5 is fast, ChatGPT is cheap

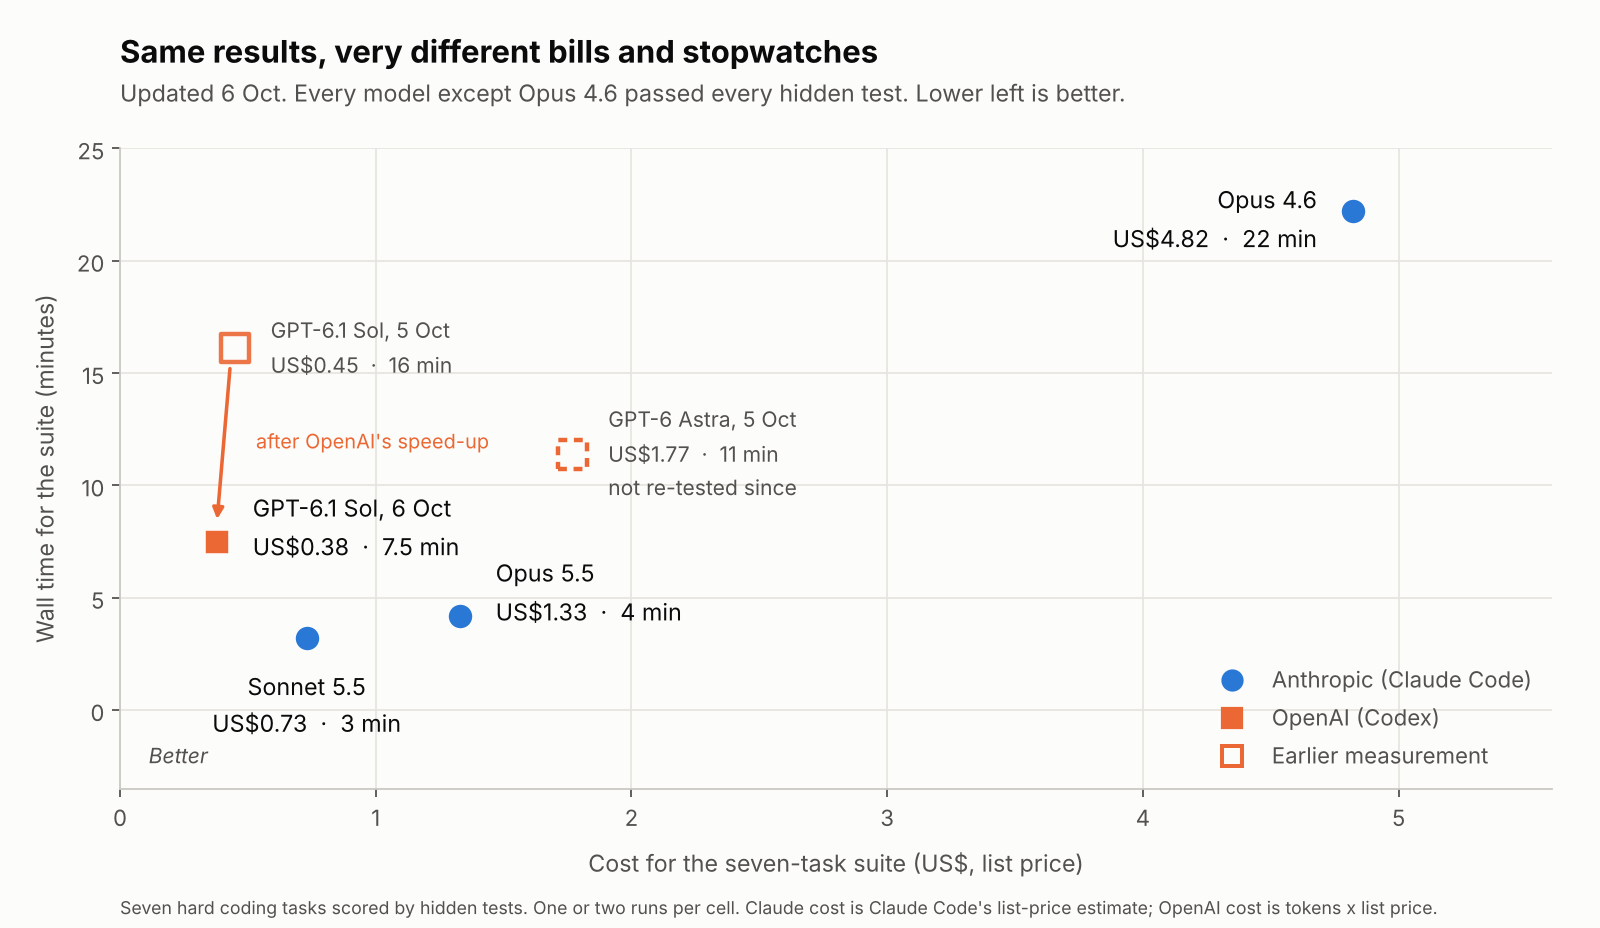
I ran the same seven hard coding tasks through five models. Every current model passed every test. The only things that differed were the bill and the stopwatch.

Update, 6 October, 4 pm. Hours after I published, OpenAI made GPT-6 Astra and GPT-6.1 Sol about 50% faster by default for people signed in with ChatGPT. I re-ran the Sol suite this afternoon and have corrected the numbers below. Old figures are struck through. Cost, token use, pass rate and quota burn did not change. I have not re-tested Astra.

Continue reading →


Chinese EV production consolidation?

“China’s many new car brands can build a combined 40 million vehicles per year, far exceeding domestic demand of under 20 million and exports of around 10 million. A consolidation process seems inevitable.” - spotted via the weekly valuable Dense Discovery newsletter


The parasite buried in Alan Kohler's AI column

The most interesting answer in Alan Kohler’s column this morning came from a Chinese AI model.

Kohler’s analysis piece for ABC News argues that “Artificial Intelligence” is the wrong name for what is being built, that “Other Intelligence” would serve us better, and that we are creating a new form of life. This post is only a pointer. The column is the thing, and you should read all of it.

Continue reading →


Worth reading - The biggest risk everyone already knows about

The AI spending boom can’t last. The harder question is when it ends, and Ben Carlson’s answer is an uncomfortable one: in past booms, stock markets have tended to peak before the capex spending slows. By the time the big spenders pull back, the market has already moved on. Carlson writes A Wealth of Common Sense, and this piece is a calm look at one of the largest concentrated bets in history.

Continue reading →


Worth reading - The brakes are not connected

Telling an AI agent “do not access external systems” is an instruction. Not giving it network access is a brake. Mark Gibbs hangs a whole argument on that difference, and it’s a sharp one. Gibbs, writing for TidBITS, takes the two comfort blankets of the AI safety debate (slow it down, keep a human in the loop) and asks whether either one actually stops anything. He’s in favour of both. He just doesn’t think either is a brake.

Continue reading →


Jev and the rise of the cheap decision model

A start-up built an AI that cannot write a single sentence, and within weeks OpenAI and Cloudflare had built one too. Here is what Jev does, why it costs a sliver of what ChatGPT-style models charge and who is already using it. All dollar figures are US dollars.

Not three weeks ago, almost nobody outside the developer world had heard of Jev. This week, TechCrunch reported that OpenAI had announced its own version, and the headline called it a Jev clone.

Continue reading →


Skills ain't skills

Google announced Skills for Gemini yesterday. Same word as the Skills in Claude, ChatGPT and Microsoft’s Cowork. Different thing.

In a post on Google’s blog, Gemini product manager Deven Tokuno describes Skills as reusable custom instructions. You save them once and call them by typing a forward slash and the skill’s name. You can build one from an existing chat, stack several together and attach reference files such as PDFs and images. Sharing is promised, with details to come.

Continue reading →