A start-up built an AI that cannot write a single sentence, and within weeks OpenAI and Cloudflare had built one too. Here is what Jev does, why it costs a sliver of what ChatGPT-style models charge and who is already using it. All dollar figures are US dollars.
Not three weeks ago, almost nobody outside the developer world had heard of Jev. This week, TechCrunch reported that OpenAI had announced its own version, and the headline called it a Jev clone.
Jev is the first product from TypeSafe AI, a start-up led by former OpenAI engineer Diogo Almeida. The speed of the imitation tells you something. Somebody found a gap in how AI gets used, and the big players noticed at once.
What Jev actually does
ChatGPT, Claude and Gemini are large language models, or LLMs. You give them words and they write words back. Jev writes nothing. TypeSafe calls it a System One model: software hands it a situation and a question, and it answers in one of three ways. It picks one option from a list you define, places something on a scale you define or gives the probability that a yes or no statement is true.
Feed it a message saying checkout has failed for every customer for the past hour and it returns something like this: urgent, 97 per cent likely; send to the technical team, 94 per cent sure. No chat, no explanation, just labels and numbers that ordinary software can act on.
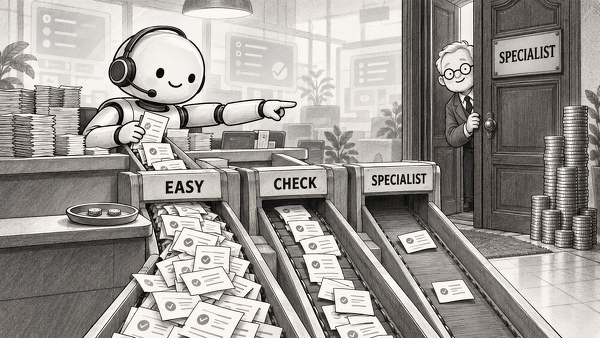
Think of a triage nurse rather than a consultant. A consultant hands you a considered paragraph, and your program then has to dig the answer out of it and hope the model stuck to your categories. The nurse sorts each arrival in a fraction of a second and says how confident she is. Your software stays in charge and decides whether to route, escalate or call the expensive specialist.
Why it costs so little
LLMs bill by the token, roughly a word fragment, for what they read and again for what they write. Writing is the slow, expensive part, because the model produces its answer one fragment at a time.
Jev charges $0.042 per million input tokens and nothing for output, because its answers are values rather than a stream of text. At that rate a 1,000-token support ticket costs about $0.000042 to judge.
TypeSafe has not published how Jev is built, so this part is informed speculation. The likeliest explanation is a small model that scores the available answers in one pass rather than composing a reply. Cloudflare describes its rival, Clef, exactly that way, as a non-autoregressive decision step on an open model.
The best evidence is a test from MotherDuck, a database company that built Jev into its SQL tool. It sorted 100,000 news articles into four topics. Jev cost $0.50, took 40 seconds and scored 89 per cent. GPT-4o mini cost $1.93, took 19 minutes 45 seconds and scored 80 per cent. GPT-5.6 Terra, a far bigger model, cost $37.58, took nearly 32 minutes and scored 88 per cent.
Two caveats. MotherDuck is a partner, not a neutral referee, and it drew the articles from the training portion of a public dataset. TypeSafe’s headline claim of 444.6 times cheaper and 193.6 times faster comes from its own workflow tests, and the MarkTechPost coverage tells readers to test on their own data.
Where it fits
Think of the front door, not the consulting room. A cheap decision model looks at every request, deals with the easy majority and passes only the hard or uncertain cases to a big LLM or a human.
The sharpest use is watching AI agents, the programs that take actions on your behalf. Checking every action with a frontier model gets expensive quickly. TechCrunch reports a demo by Shapor Naghibzadeh of QueryStory that checked each agent action against its task for $2.94 with Jev, versus $372 with a frontier LLM. That is the difference between monitoring everything and monitoring nothing.
Speculation: if that pattern holds, the big models become the specialists you pay for rarely, and the bulk of AI traffic moves to cheap deciders.
Who is using it
Named customers are thin on the ground, so treat these as early tests rather than mature deployments. Per MarkTechPost, Vercel chief executive Guillermo Rauch reported Jev was up to 18 times faster than OpenAI’s Luna model at the 95th percentile (the slow end, where 95 per cent of requests finish faster), and more accurate. He also noted one reviewing step still ran on Luna. Bryo AI’s chief technology officer, Nikhil Mudholkar, found Gemini slightly more accurate for email triage but 10 to 20 times more expensive.
Agents are the other early adopter. A Google Flights search finished in about seven seconds, and Droidrun’s phone agent drove Uber on a real Android handset, nine actions in about 21 seconds. No booking was completed, which is a useful reminder of where the technology still sits.
The clone wars
OpenAI’s Decisions API is a limited preview built on its Luna model, with no published pricing. Cloudflare released Clef and Clef-flash as open models under an Apache 2.0 licence, reporting median response times of 209 and 39 milliseconds against 524 for Jev, and says Clef beat Jev on three of four of TypeSafe’s own workflow tests. That is Cloudflare’s testing, not an independent check.
Almeida told TechCrunch that fast and cheap is easy and intelligence is the hard part, and his bet is that Jev’s synthetic training data gives it a reliability the clones lack. Speculation: when a feature can be cloned in weeks, that lead is measured in months.
A tidy answer is not a correct one, and most of the numbers above come from vendors or their partners. If your business pays a large model to answer yes or no questions all day, find out what that costs. The expensive brain should be the second opinion, not the receptionist.
Sources:
- OpenAI’s Jev clone could help the frontier lab stop its swarming agents - TechCrunch
- Clef and Clef-flash decision models - Cloudflare
- TypeSafe AI releases Jev - MarkTechPost
- MotherDuck supports Jev - MotherDuck
- System One concepts - TypeSafe documentation